A final-year Ph.D. student at National Taiwan University advised by Prof. Hung-yi Lee, working on efficiency, interpretability, and fine-tuning of large pre-trained speech models, with hands-on experience in large-scale LLM pre-training. Authored eight first-author papers at top-tier venues (IEEE TASLP, ACL, INTERSPEECH, IEEE ASRU, IEEE SLT); IEEE ASRU 2025 Best Student Paper Finalist.
🔥 News
- 2026.09: 🎉🎉 One paper accepted at IEEE SLT 2026! See you in Sicily 🇮🇹!
- 2026.06: 🎉🎉 Two papers accepted at INTERSPEECH 2026!
- 2026.04: 🎉🎉 Two papers accepted at ACL 2026 (1 main conference, 1 findings)! See you in San Diego 🇺🇸🏖️🐻❄️!
- 2025.11: 🎉🎉 Journal accepted at IEEE Transactions on Audio, Speech and Language Processing (TASLP)! Will be presented at ICASSP 2026. See you in Spain 🇪🇸!
📖 Education
- National Taiwan University, Ph.D. in Communication Engineering, 2022 - Present
- SPML Lab, advised by Prof. Hung-yi Lee; transferred from M.S. program in Sep. 2024.
- National Taiwan University, B.S. in Computer Science and Information Engineering, 2018 - 2022
🔬 Research Experience
- Centre for Speech Technology Research, University of Edinburgh, Edinburgh, UK, Aug. 2026 - Jan. 2027
Visiting Student Researcher, mentored by Prof. Hao Tang- Uncovered fine-grained audio-text shared mechanisms by which large audio language models (LALMs) comprehend acoustic attributes such as emotion and gender, and validated their causal role.
- MediaTek Research, Taipei, Taiwan, Jan. 2026 - Jun. 2026
Deep Learning Research Intern, mentored by Dr. Feng-Ting Liao- Pre-trained dense language models from scratch with NVIDIA Megatron, scaling up to an 8B-parameter model trained on 160B tokens with 8 NVIDIA B200 GPUs, to study alternative Transformer FFN shapes.
- 8th JSALT Summer Workshop 2022, Virtual (hosted from Baltimore, USA), Jul. 2022
Research Team Leader, mentored by Prof. Hao Tang- Simplified and compressed pre-trained speech models, showing smaller is not always faster, and extended SUPERB to assess generalization and efficiency.
📝 First-Author Publications
* indicates equal contribution.
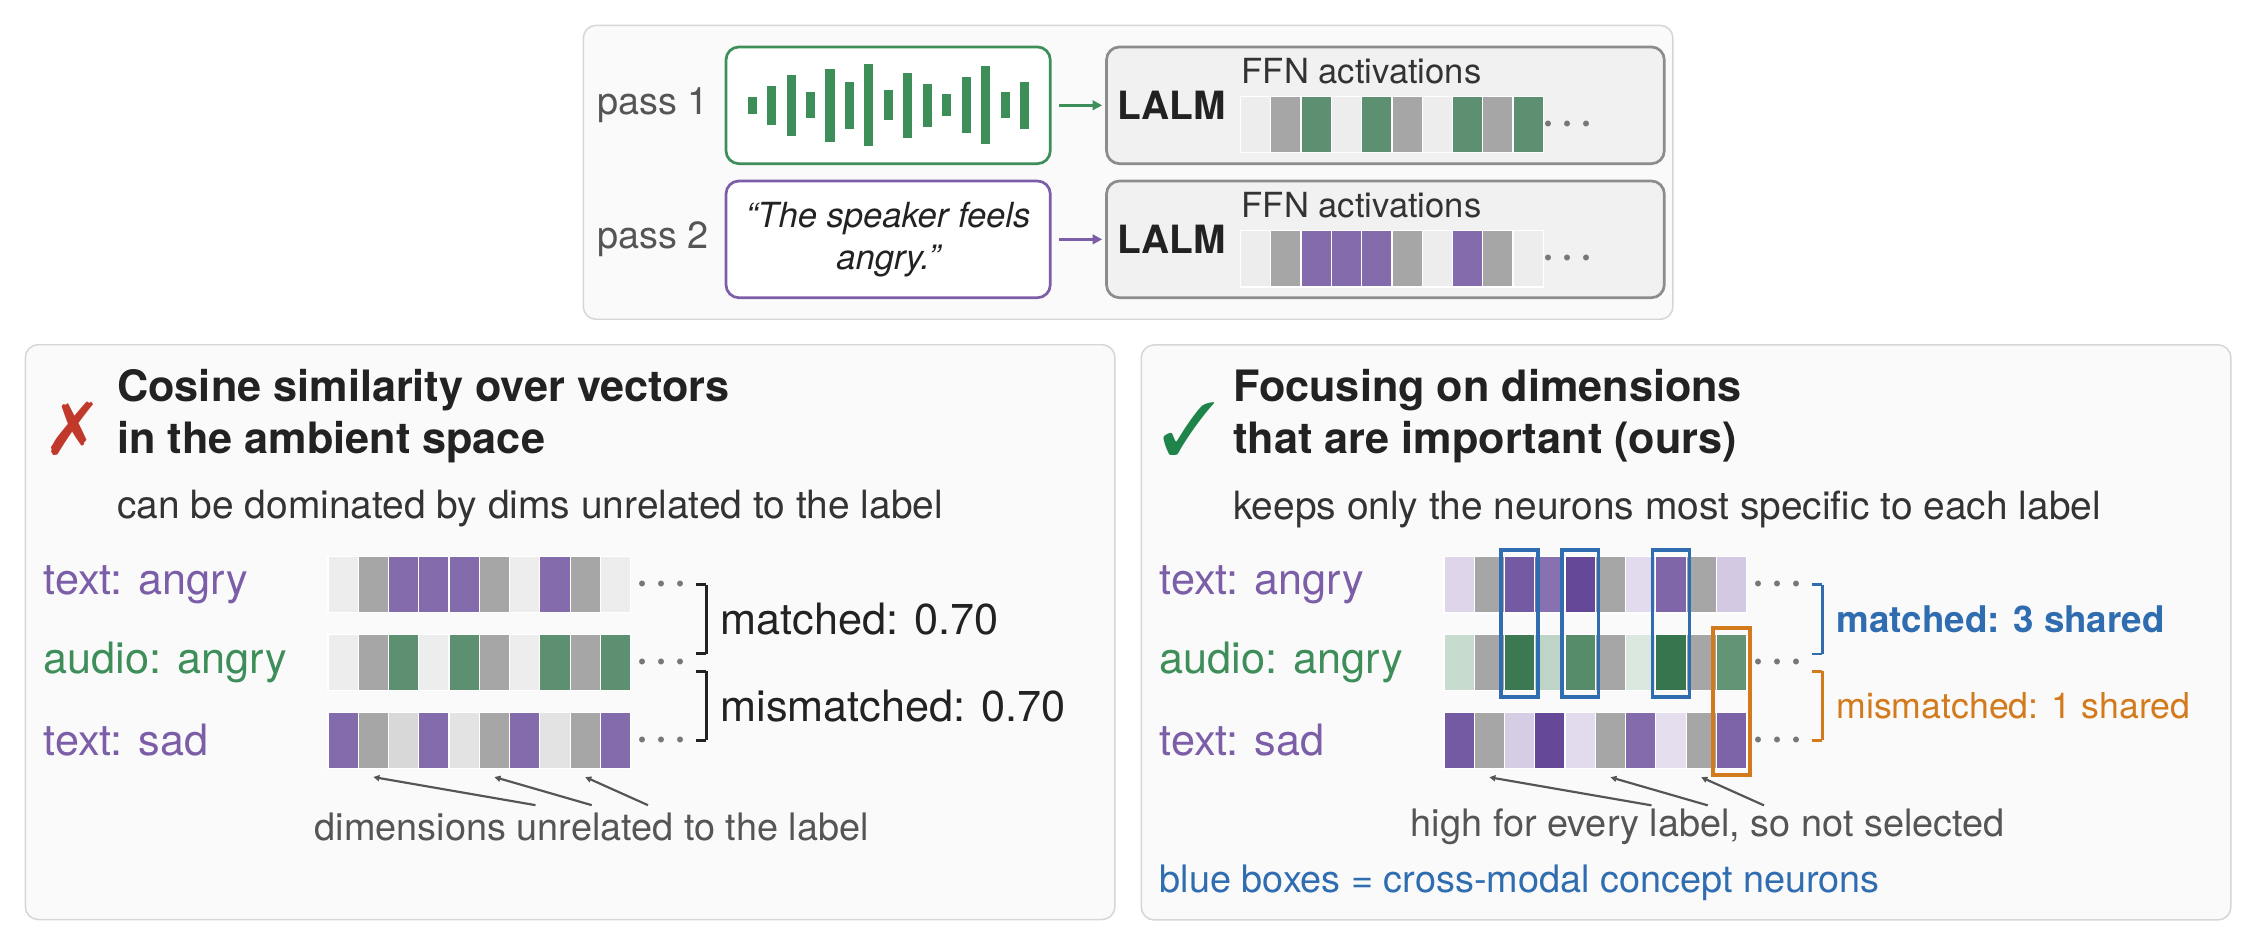
Uncovering Audio-Text Alignment in Large Audio-Language Models through Cross-Modal Concept Neurons
Tzu-Quan Lin, Chih-Kai Yang*, Yi-Cheng Lin*, Hao Tang, Hung-yi Lee. Under Review
Identified audio-text shared neurons that causally drive LALM perception of emotion and gender.
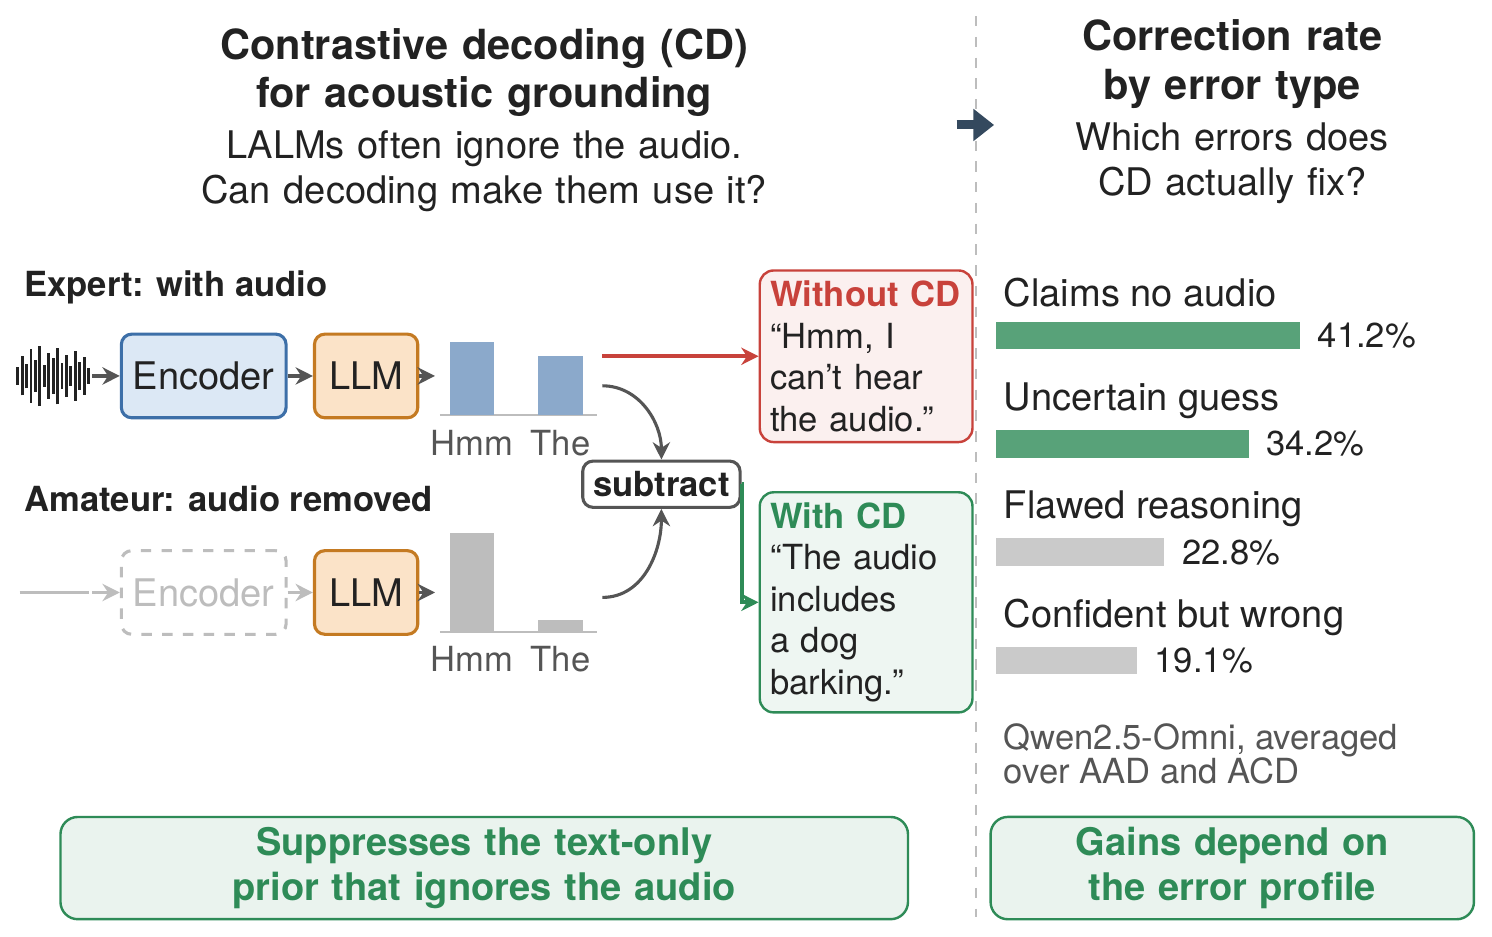
How Contrastive Decoding Enhances Large Audio Language Models
Tzu-Quan Lin, Wei-Ping Huang, Yi-Cheng Lin, Hung-yi Lee. IEEE SLT 2026 [Code]
Showed that contrastive decoding in LALMs fixes audio-blindness errors but not flawed reasoning.
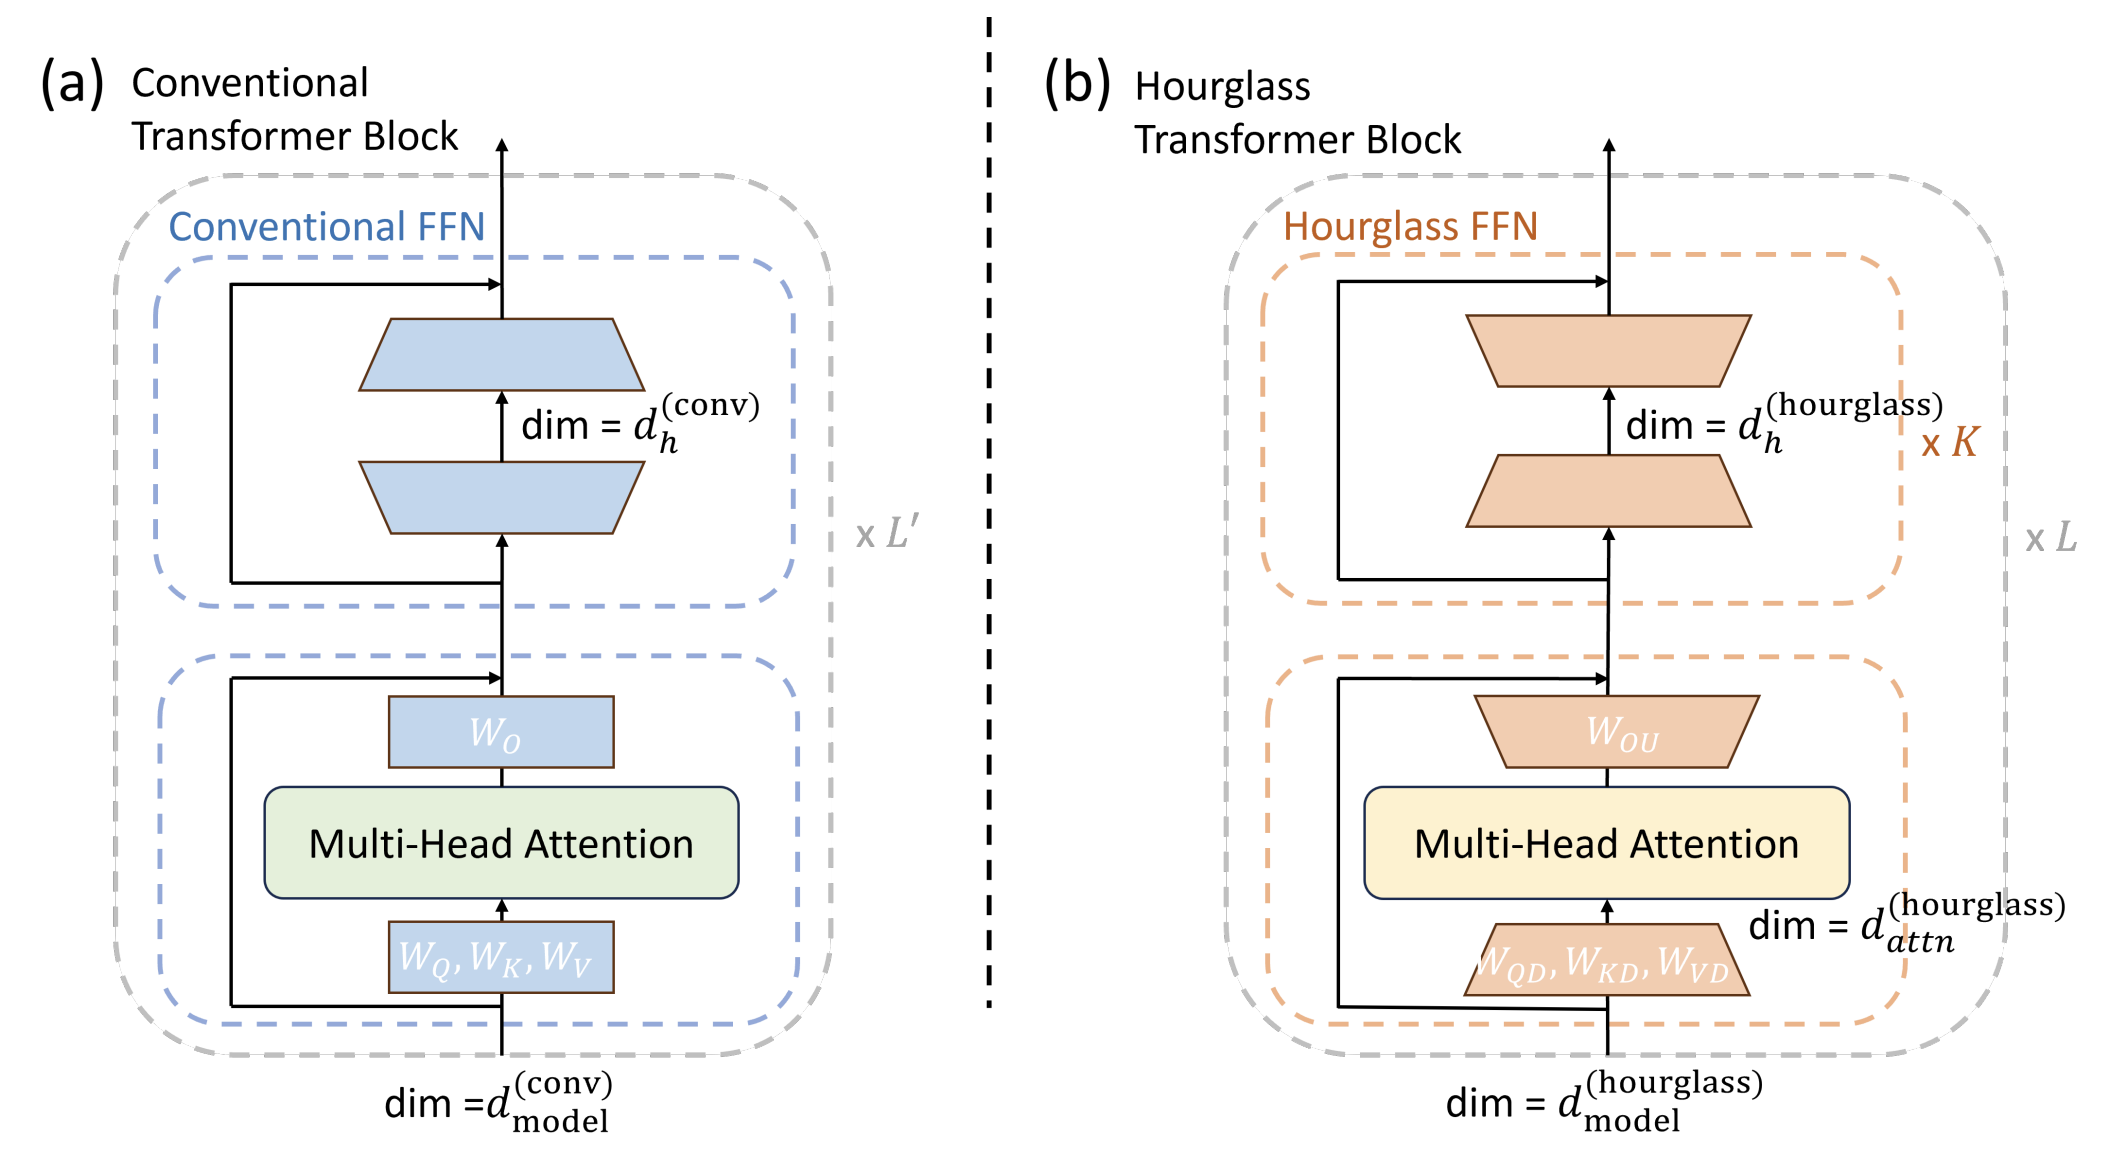
Revisiting the Shape Convention of Transformer Language Models
Feng-Ting Liao*, Guan-Ting Yi*, Tzu-Quan Lin*, Meng-Hsi Chen, Da-shan Shiu. Under Review
Hourglass FFNs match standard Transformers with 8.7% less training compute and half the KV cache.
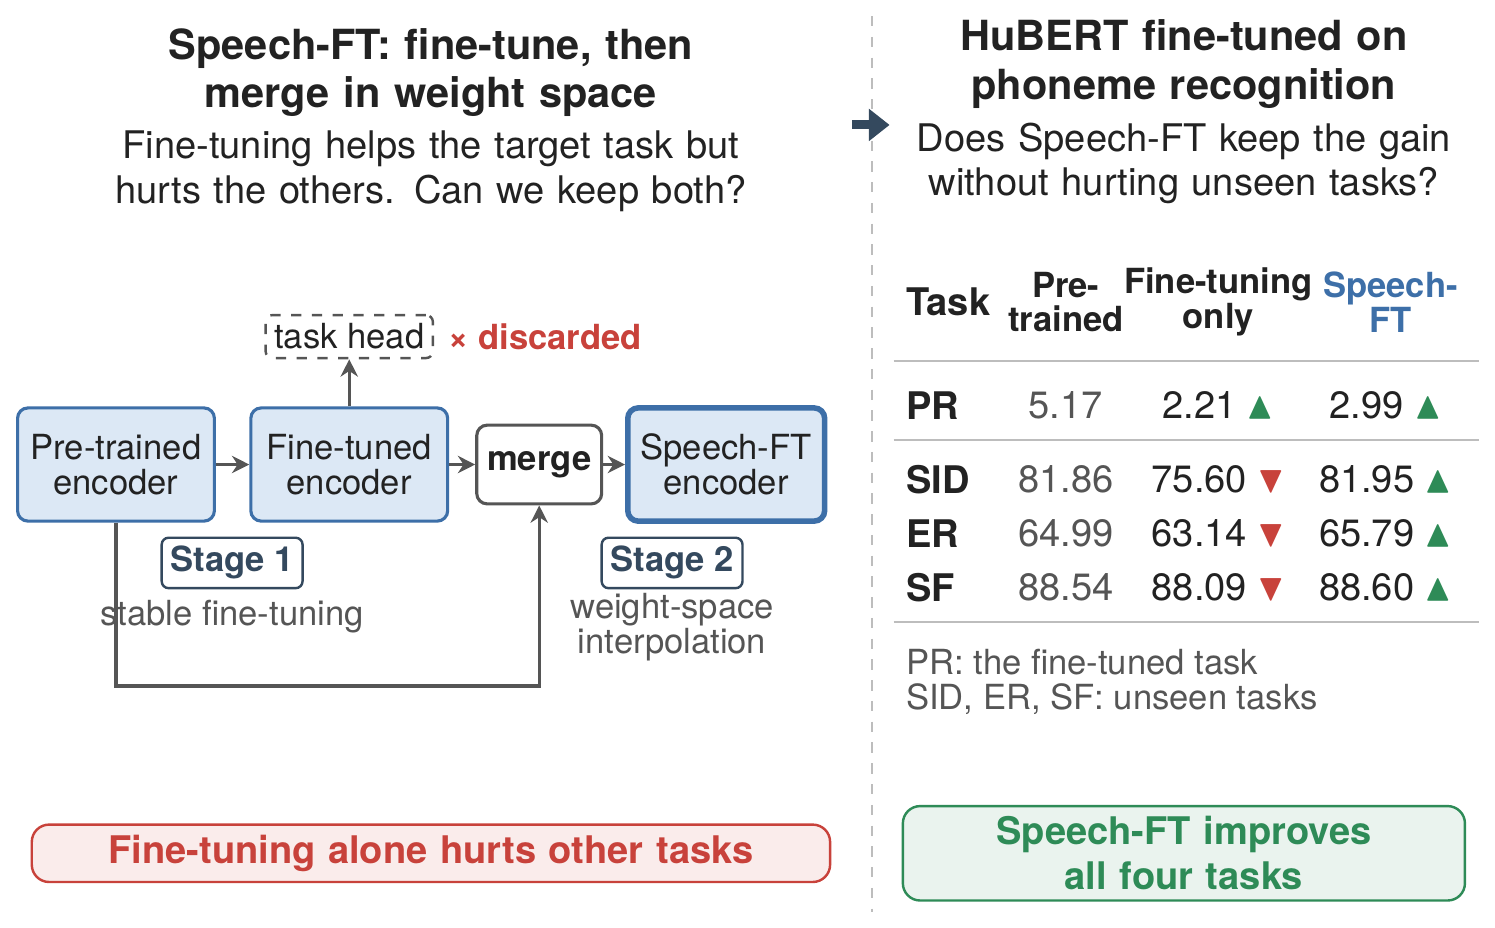
Tzu-Quan Lin, Wei-Ping Huang, Hao Tang, Hung-yi Lee. IEEE TASLP [Code]
Uses model merging so fine-tuning strengthens pre-trained speech encoder representations across tasks.
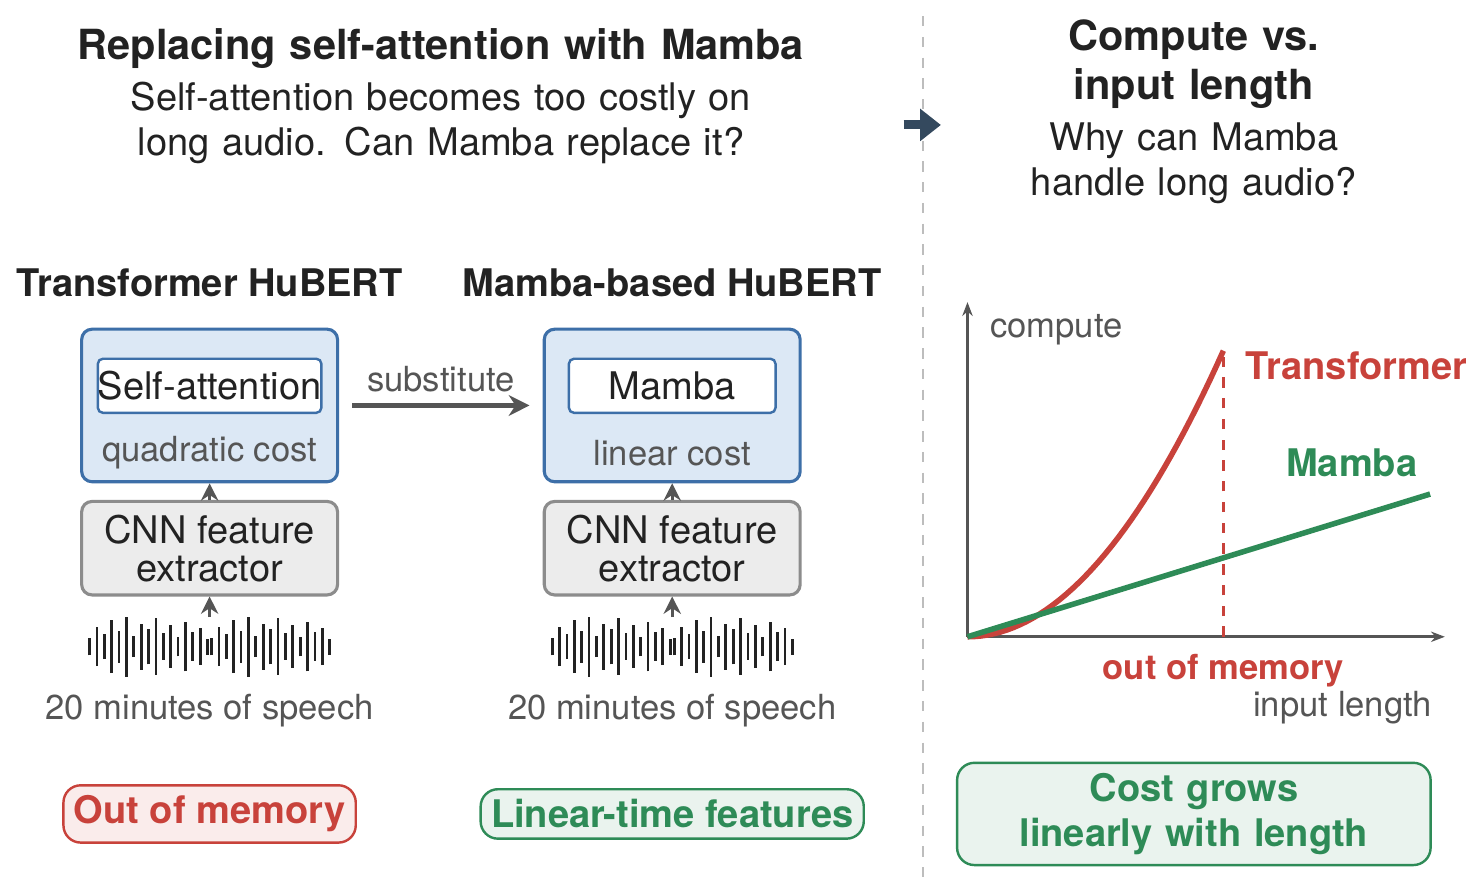
An Exploration of Mamba for Speech Self-Supervised Models
Tzu-Quan Lin*, Heng-Cheng Kuo*, Tzu-Chieh Wei, Hsi-Chun Cheng, Chun-Wei Chen, Hsien-Fu Hsiao, Yu Tsao, Hung-yi Lee. ACL 2026 Main Conference
Showed Mamba-based speech SSL models excel at long-sequence, real-time, and unit extraction tasks.
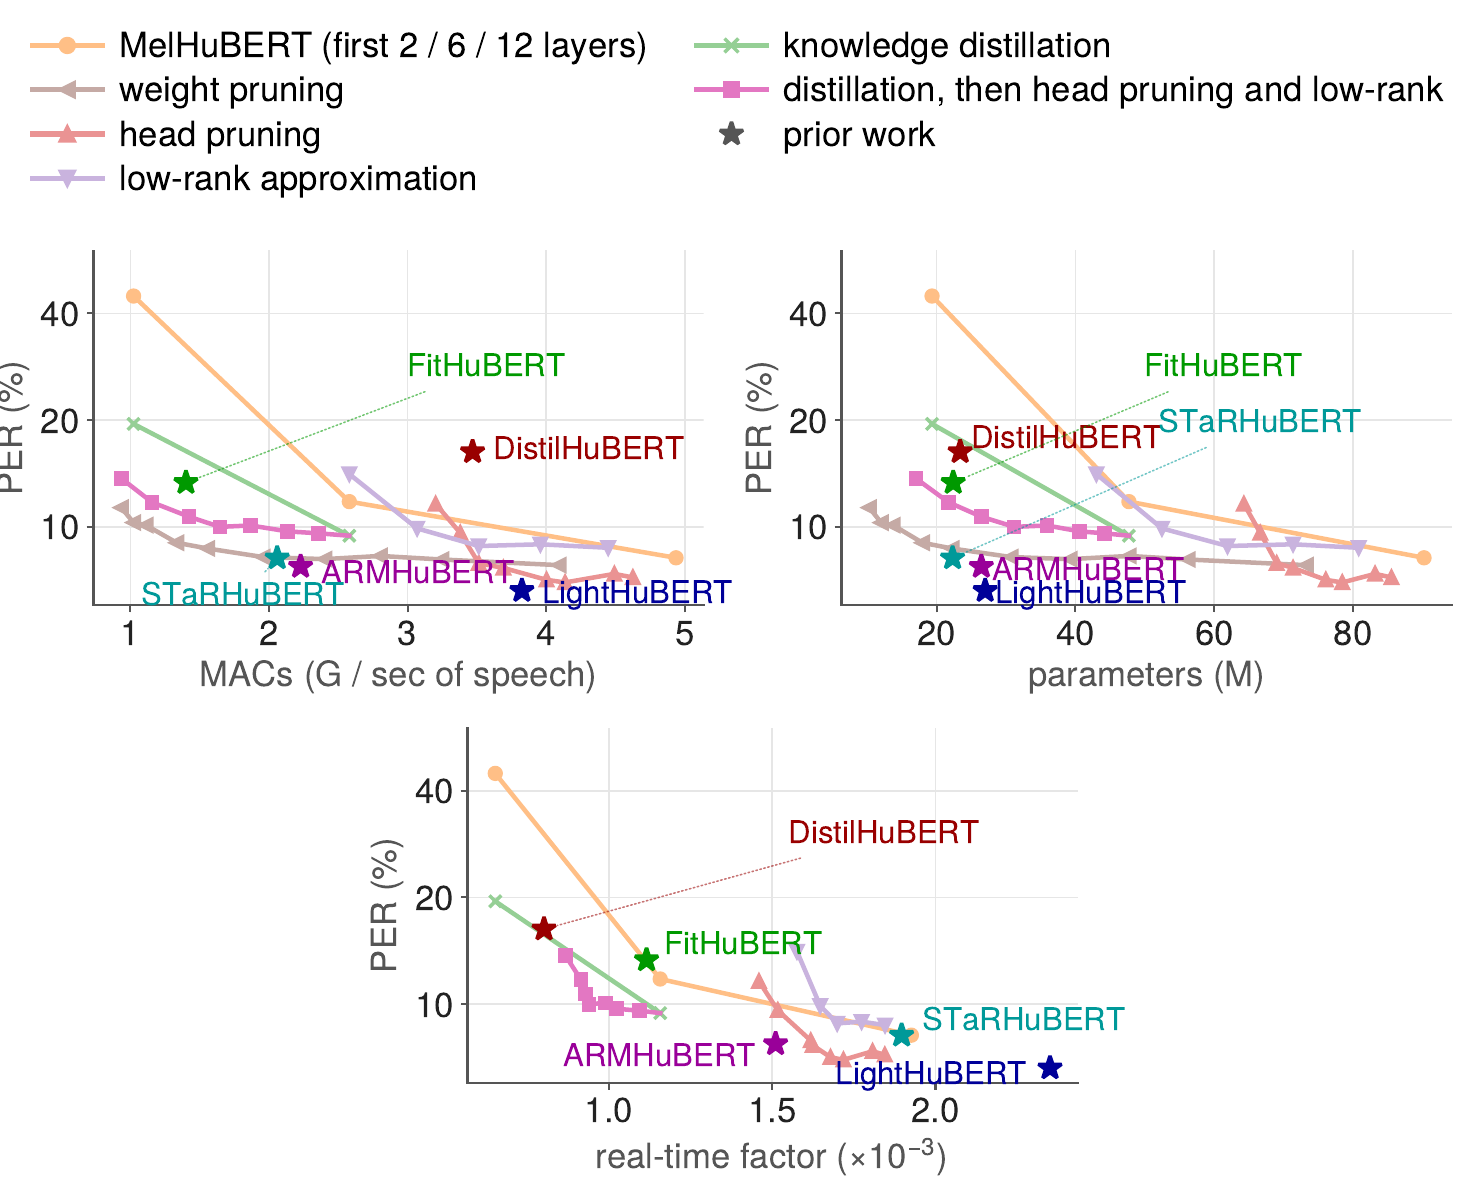
Is Smaller Always Faster? Tradeoffs in Compressing Self-Supervised Speech Transformers
Tzu-Quan Lin, Tsung-Huan Yang, Chun-Yao Chang, Kuang-Ming Chen, Tzu-hsun Feng, Hung-yi Lee, Hao Tang. IEEE ASRU 2025, Best Student Paper Finalist [Code]
Showed that smaller pre-trained speech models are not always faster across compression methods.
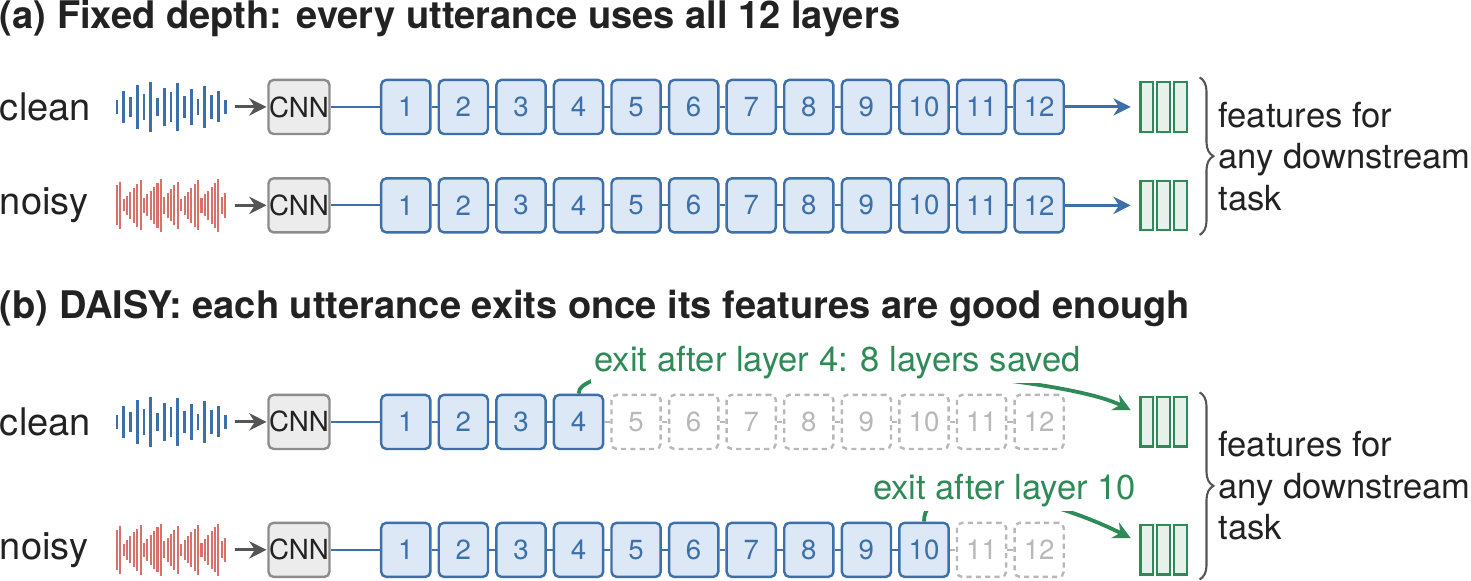
DAISY: Data Adaptive Self-Supervised Early Exit for Speech Representation Models
Tzu-Quan Lin, Hung-yi Lee, Hao Tang. INTERSPEECH 2024
Proposed an early exit method that speeds up HuBERT with minimal performance loss.
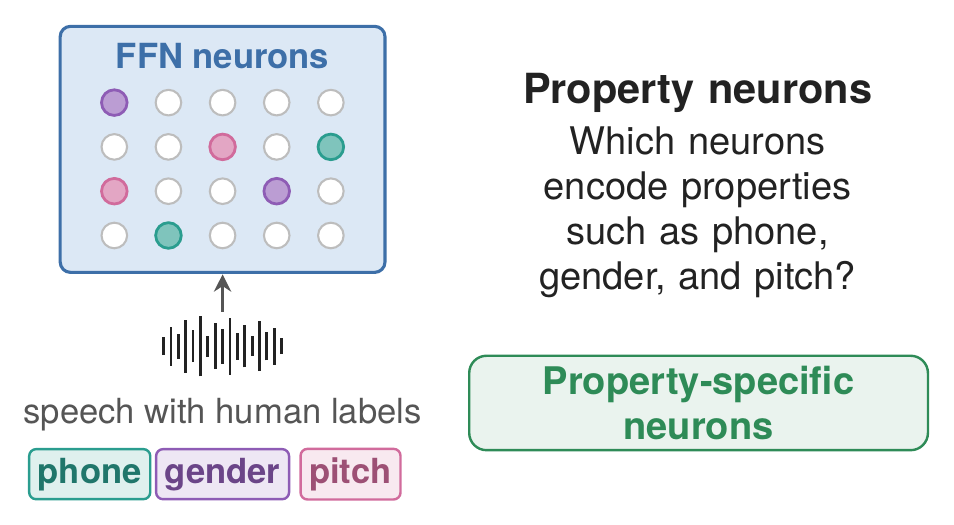
Property Neurons in Self-Supervised Speech Transformers
Tzu-Quan Lin, Guan-Ting Lin, Hung-yi Lee, Hao Tang. IEEE SLT 2024 [Code]
Identified feed-forward neurons that store speech properties such as phones, gender, and pitch.
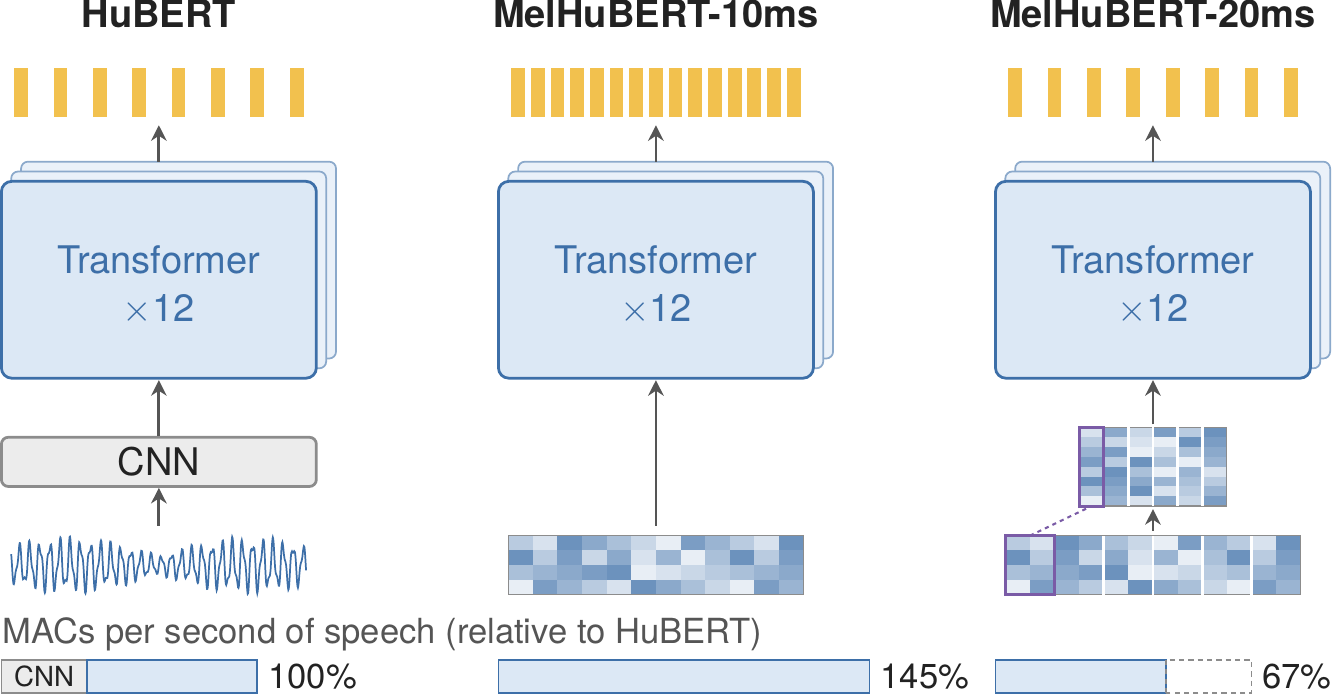
MelHuBERT: A Simplified HuBERT on Mel Spectrograms
Tzu-Quan Lin, Hung-yi Lee, Hao Tang. IEEE ASRU 2023 [Code]
Studied how to simplify pre-trained speech models while maintaining comparable performance.
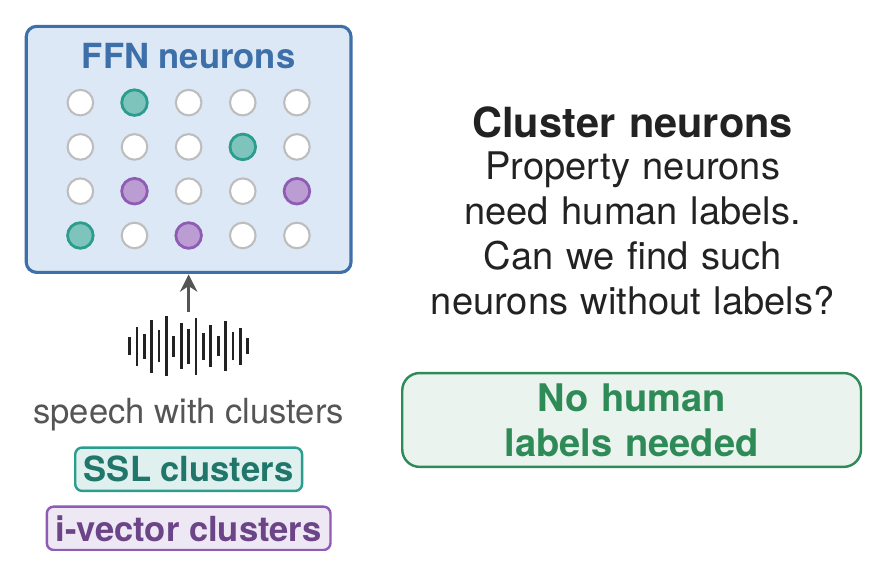
Identifying Speaker Information in Feed-Forward Layers of Self-Supervised Speech Transformers
Tzu-Quan Lin, Hsi-Chun Cheng, Hung-yi Lee, Hao Tang. APSIPA ASC 2025
Identified speaker-related neurons in the feed-forward layers of pre-trained speech models.
📄 Other Publications
- DeSTA2.5-Audio: Toward General-Purpose Large Audio Language Model with Self-Generated Cross-Modal Alignment. IEEE TASLP
- CAAD: Contrastive Audio-Aware Distillation for Efficient Speech Language Models. INTERSPEECH 2026
- AdaLTM: Adaptive Layer-wise Task Vector Merging for Categorical Speech Emotion Recognition with ASR Knowledge Integration. INTERSPEECH 2026
- Pseudo2Real: Task Arithmetic for Pseudo-Label Correction in Automatic Speech Recognition. ACL Findings 2026
- Dynamic-SUPERB Phase-2: A Collaboratively Expanding Benchmark for Measuring the Capabilities of Spoken Language Models with 180 Tasks. ICLR 2025
- On the Social Bias of Speech Self-Supervised Models. INTERSPEECH 2024
- Listen and Speak Fairly: A Study on Semantic Gender Bias in Speech Integrated Large Language Models. IEEE SLT 2024
- SUPERB @ SLT 2022: Challenge on Generalization and Efficiency of Self-Supervised Speech Representation Learning. IEEE SLT 2022, Best Paper Finalist
🏆 Honors and Awards
- 2025, IEEE ASRU 2025 Best Student Paper Finalist (top 11 of 215 accepted papers)
- 2025, CTCI Research Scholarship ($5,000 USD; one recipient per institute)
- 2024, INTERSPEECH 2024 Best Paper Runner-up, special session (2nd author)
- 2024, ISCA Travel Grant (1,000 EUR for INTERSPEECH 2024)
- 2024, GICE Elite Doctoral Scholarship (4 years, NTU GICE & DELTA)
- 2024, MOE Doctoral Scholarship (3 years, Ministry of Education, Taiwan)
- 2022, IEEE SLT 2022 Best Paper Finalist (6 of 363 accepted papers; 5th of 14 authors)
📚 Academic Services and Teaching
- 2024 - 2026, Reviewer for NeurIPS, EMNLP, EACL, ICASSP, INTERSPEECH, SLT, ACML, IEEE TASLP, IEEE SPL
- 2022 - 2023, Teaching Assistant for 3 NTU courses, incl. Head TA of Introduction to Digital Speech Processing
🛠 Skills
- Programming: Python, C, C++, LaTeX, Git
- ML & LLM Training: PyTorch, TensorFlow, Hugging Face, Megatron-LM, NeMo, DeepSpeed
- Language: English (IELTS 7.5), Mandarin (Native)